 TypingMind×
 Hugging Face
How to use GLM-4.7-Flash with your Hugging Face API key on TypingMind
Learn how to access and use GLM-4.7-Flash with your Hugging Face API key through TypingMind. Get started with this AI model in minutes.
Efficient GLM model for fast reasoning, coding, and agent workflows
Hugging Face is the leading open-source AI platform and community hub, providing access to hundreds of thousands of models, datasets, and AI applications through its Inference Providers API.
The platform offers a unified OpenAI-compatible API endpoint (router.huggingface.co) that routes requests to multiple inference providers including Cerebras, Fireworks, Groq, Nebius, Novita, SambaNova, Together AI, and more, giving you access to top open-source models like Llama, Mistral, DeepSeek, Qwen, and Gemma.
Key features include pay-per-token pricing with free tier access, support for text generation, image generation, and multimodal models, seamless switching between inference providers, and integration with the broader Hugging Face ecosystem of tools and libraries.
See the official Hugging Face documentation for more details.
GLM-4.7-Flash Overview
| Model Name | GLM-4.7-Flash |
| Provider | Hugging Face |
| Model ID | zai-org/GLM-4.7-Flash |
| Model Logo | Get the logo URL |
| Release Date | Aug 8, 2025 |
| Last Updated | Aug 8, 2025 |
| Knowledge Cutoff | 2025-04 |
| Context Window | 200,000 tokens |
| Max Output | 128,000 tokens |
| Pricing /1M tokens | $0 input $0 output |
| Input Modalities | text |
| Output Modalities | text |
| Capabilities | ReasoningTool CallingTemperature ControlOpen Weights |
Complete Setup Guide
Get Your Hugging Face API Key
First, you'll need to obtain an API key from Hugging Face. This key allows you to access their AI models directly and pay only for what you use.
-
Go to huggingface.co and create a free account if you don't have one.
-
Open your Access Tokens settings and click + Create new token.
-
Select Fine-grained as the token type and give it a name, for example
typingmind. Under Inference, enable Make calls to Inference Providers. The other Inference permissions are only needed for dedicated Inference Endpoints.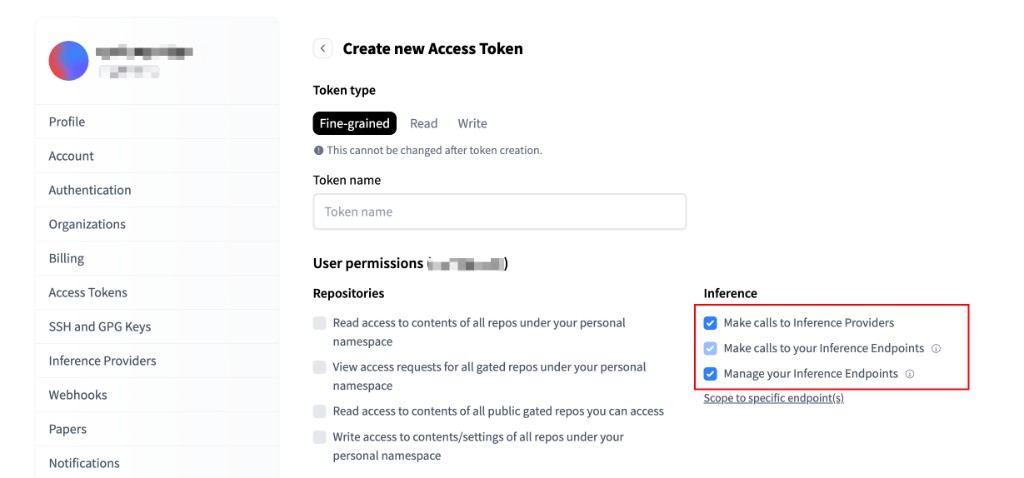
-
Click Create token and copy the token. This is your
<HF_TOKEN>.
Sometimes, this provider will require you to add a payment method to your account before you can use your API key to chat with AI. So, to avoid any hiccups, make sure you've got a payment method set up and ready to go!
Important: Keep your API key secure and never share it publicly. Store it safely as you'll need it to connect with TypingMind.
Configure TypingMind with Hugging Face API Key
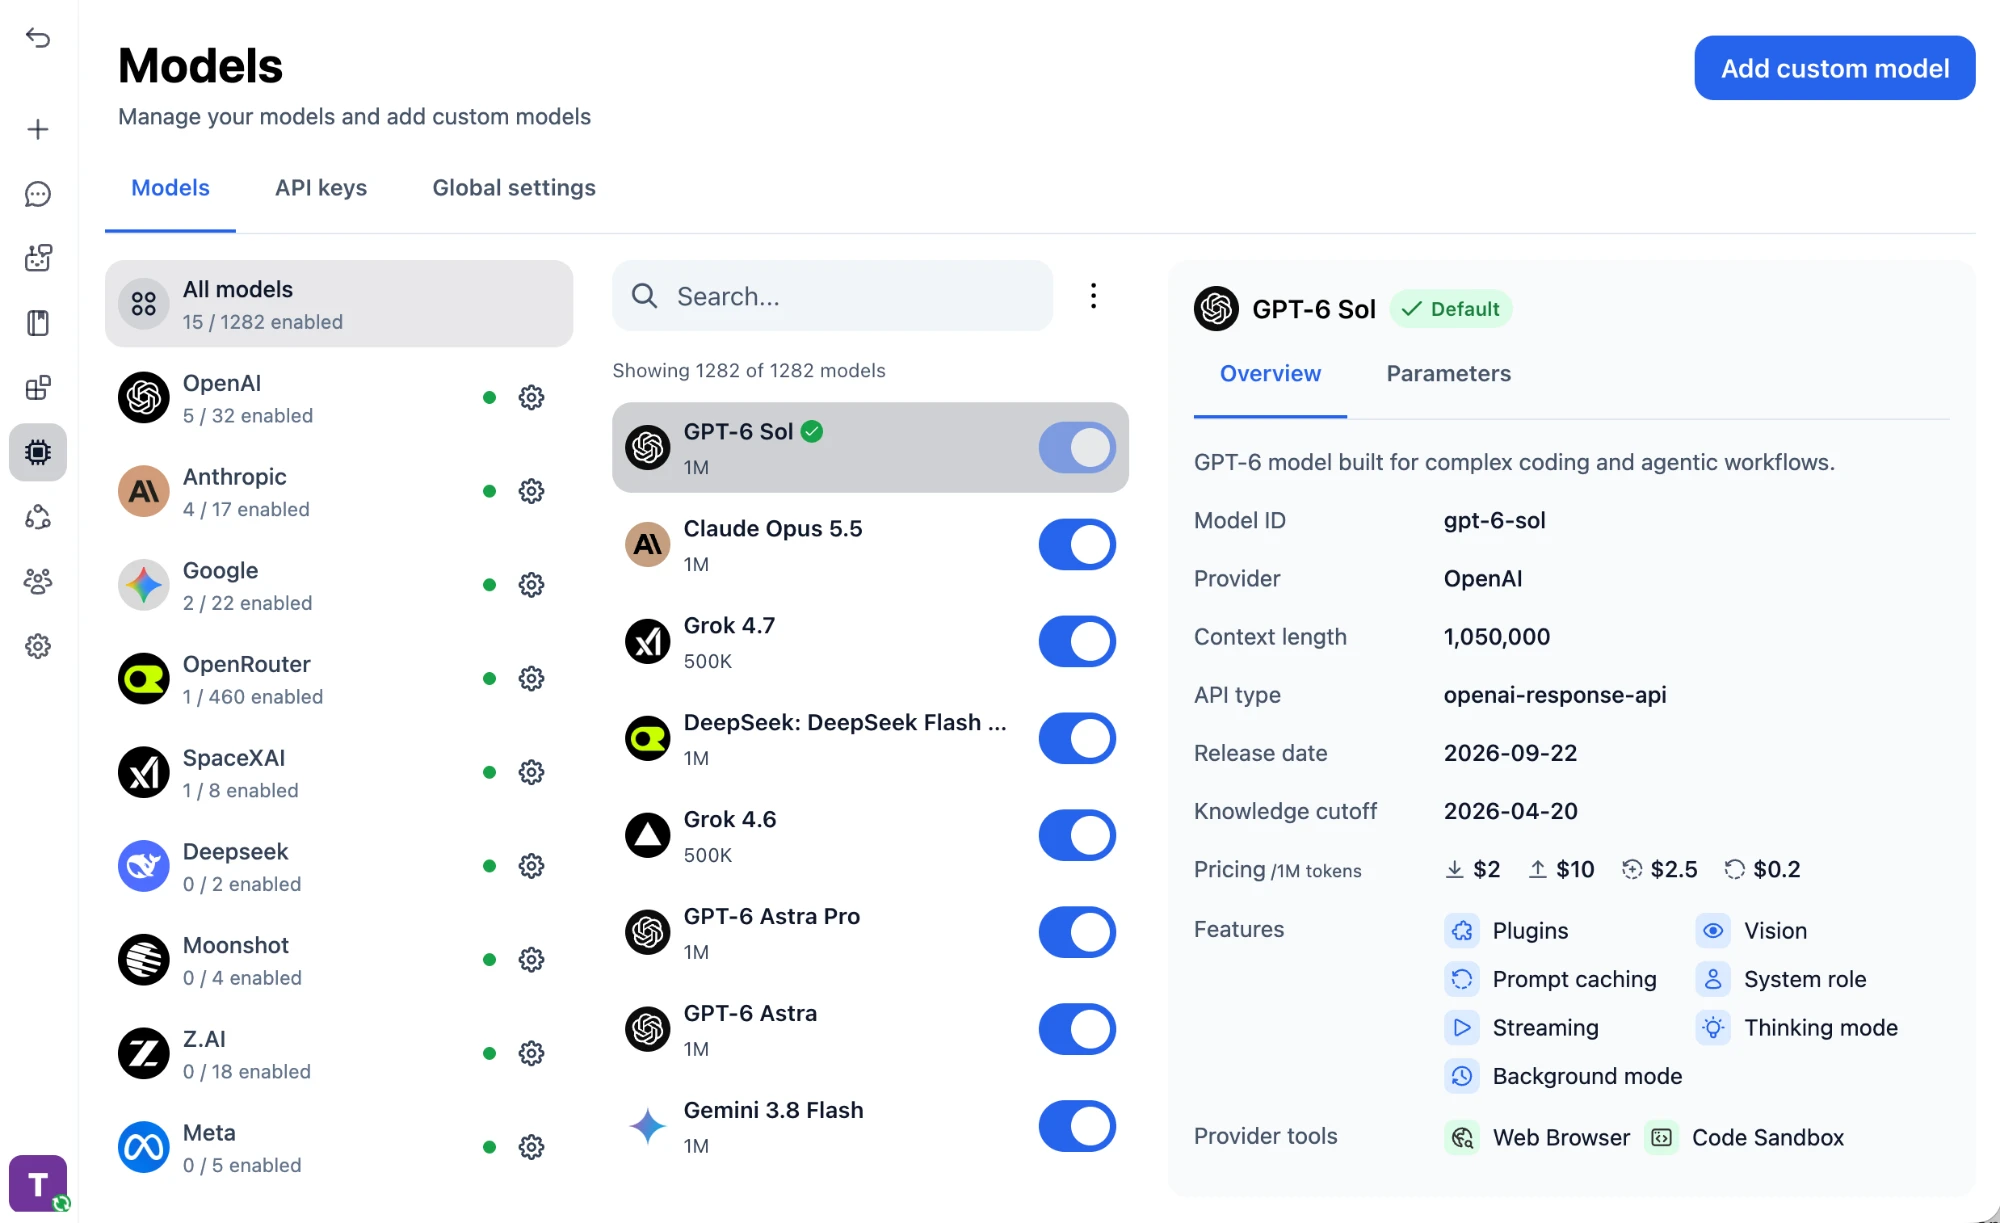
Open the Models page
Open TypingMind, click "Models" in the left sidebar, then click "Add custom model" in the top right corner.
Enter the model details
Keep "Create Manually" selected and fill in the model details:
Name:GLM-4.7-Flash via Hugging Face(or your preferred name)Model ID:zai-org/GLM-4.7-Flashfor example (check Hugging Face model list)Context Length: Enter the model's context window (e.g., 200000 for zai-org/GLM-4.7-Flash)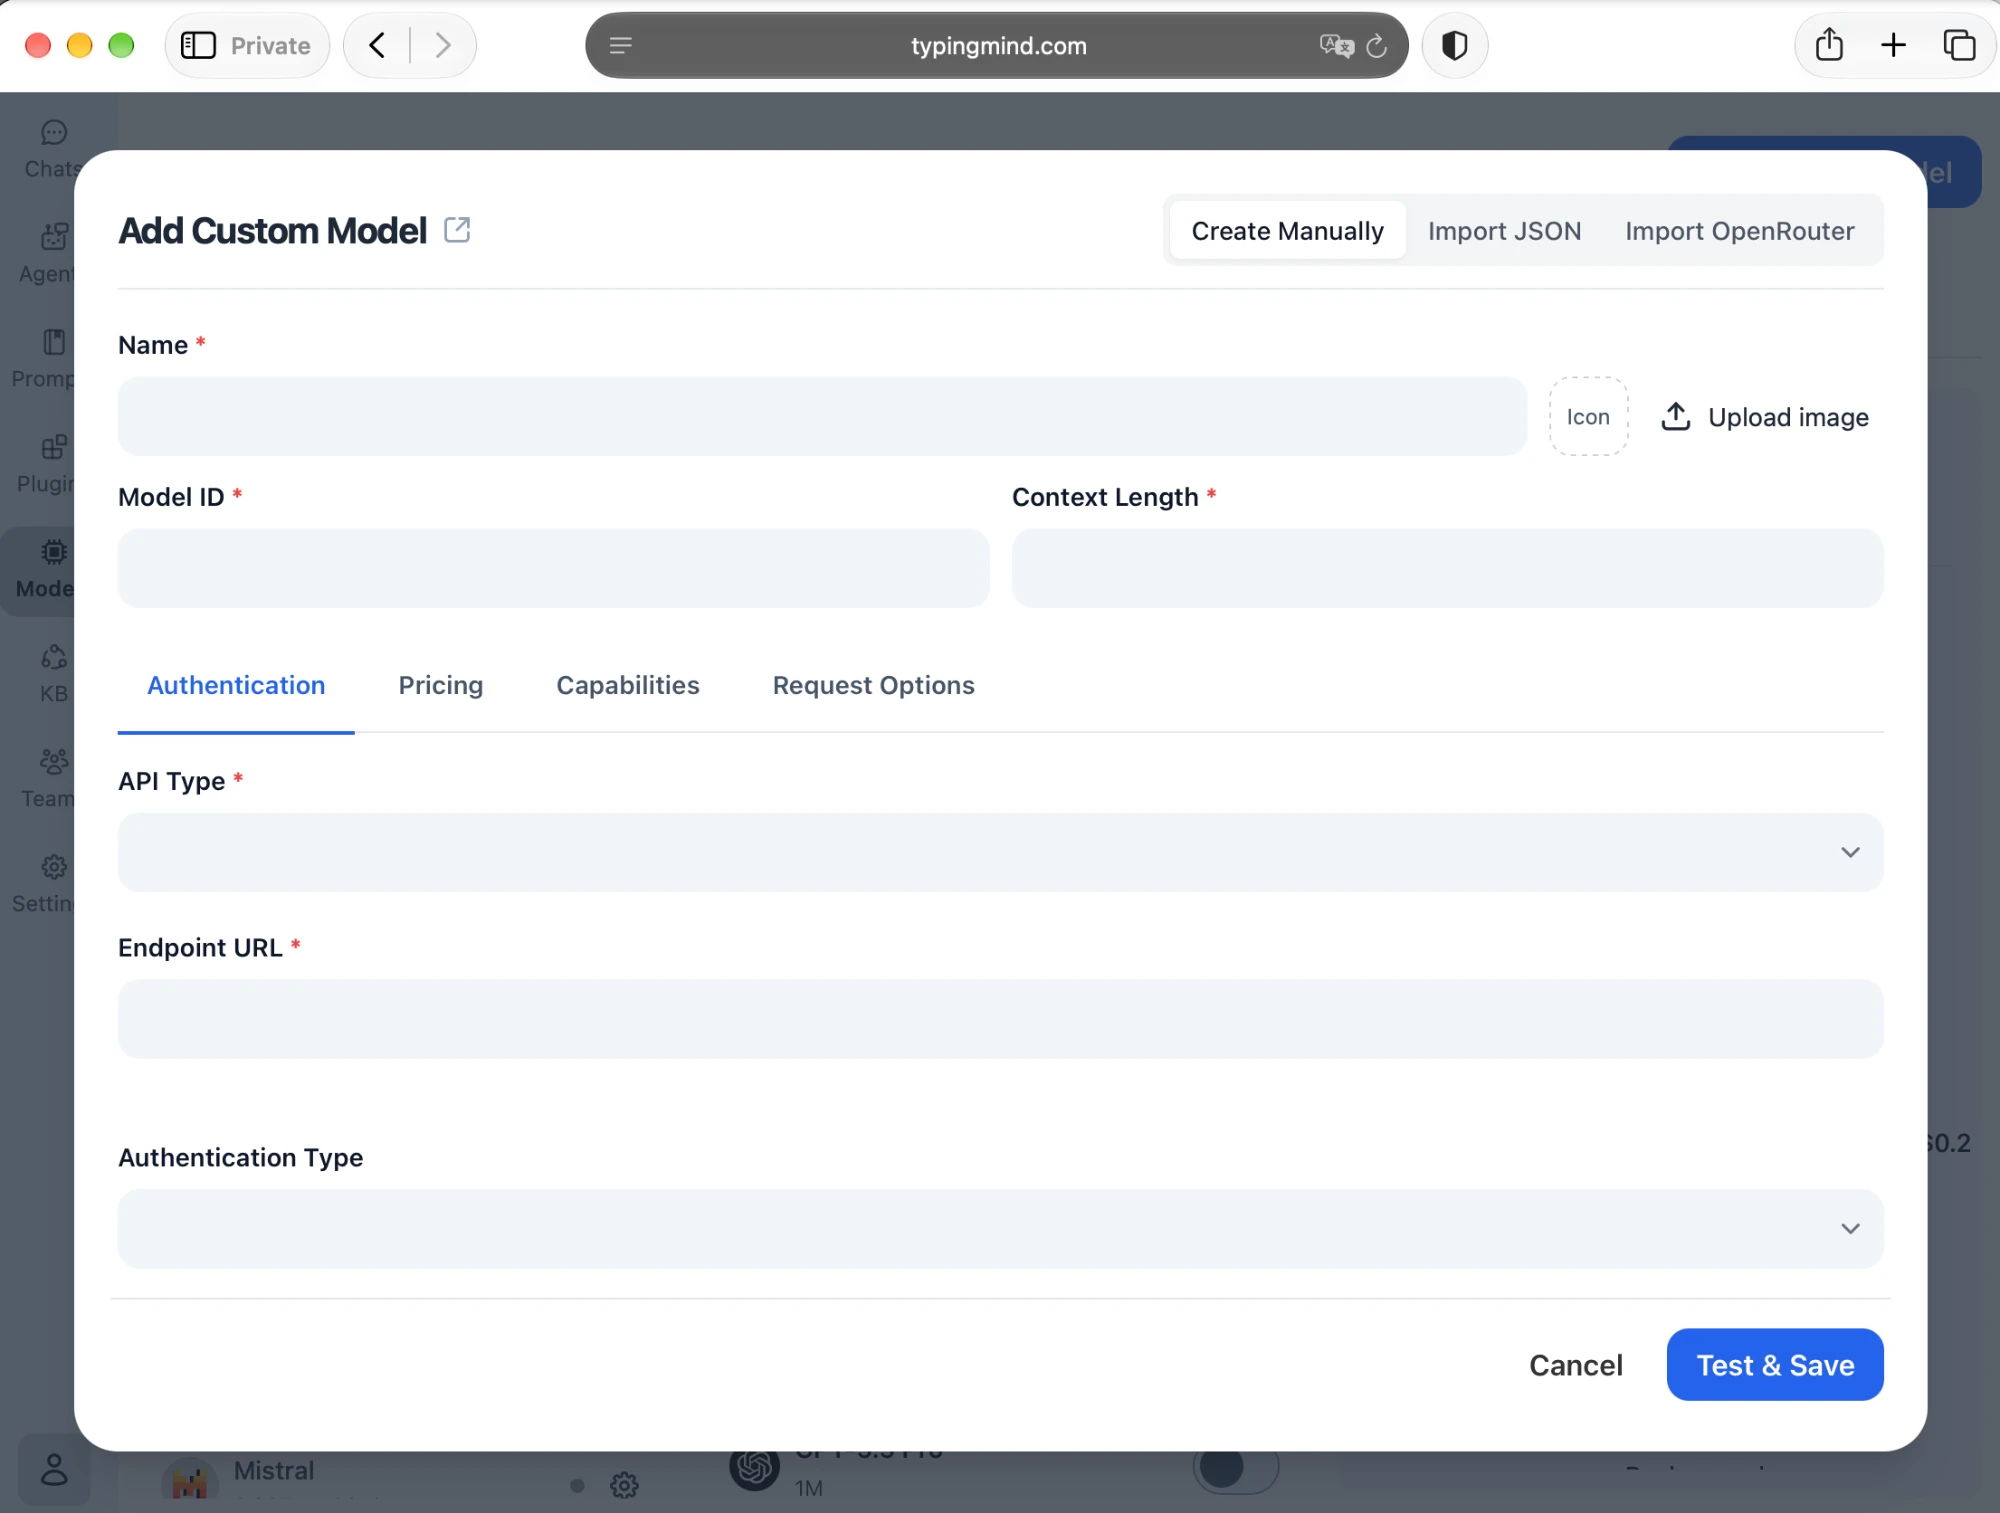
Set up authentication
In the "Authentication" tab, set the connection details:
API Type:OpenAI Chat Completions APIEndpoint URL:https://router.huggingface.co/v1/chat/completionsAuthentication Type:API Key via HTTP HeaderHeader Key:AuthorizationHeader Value:Bearer <HF_TOKEN>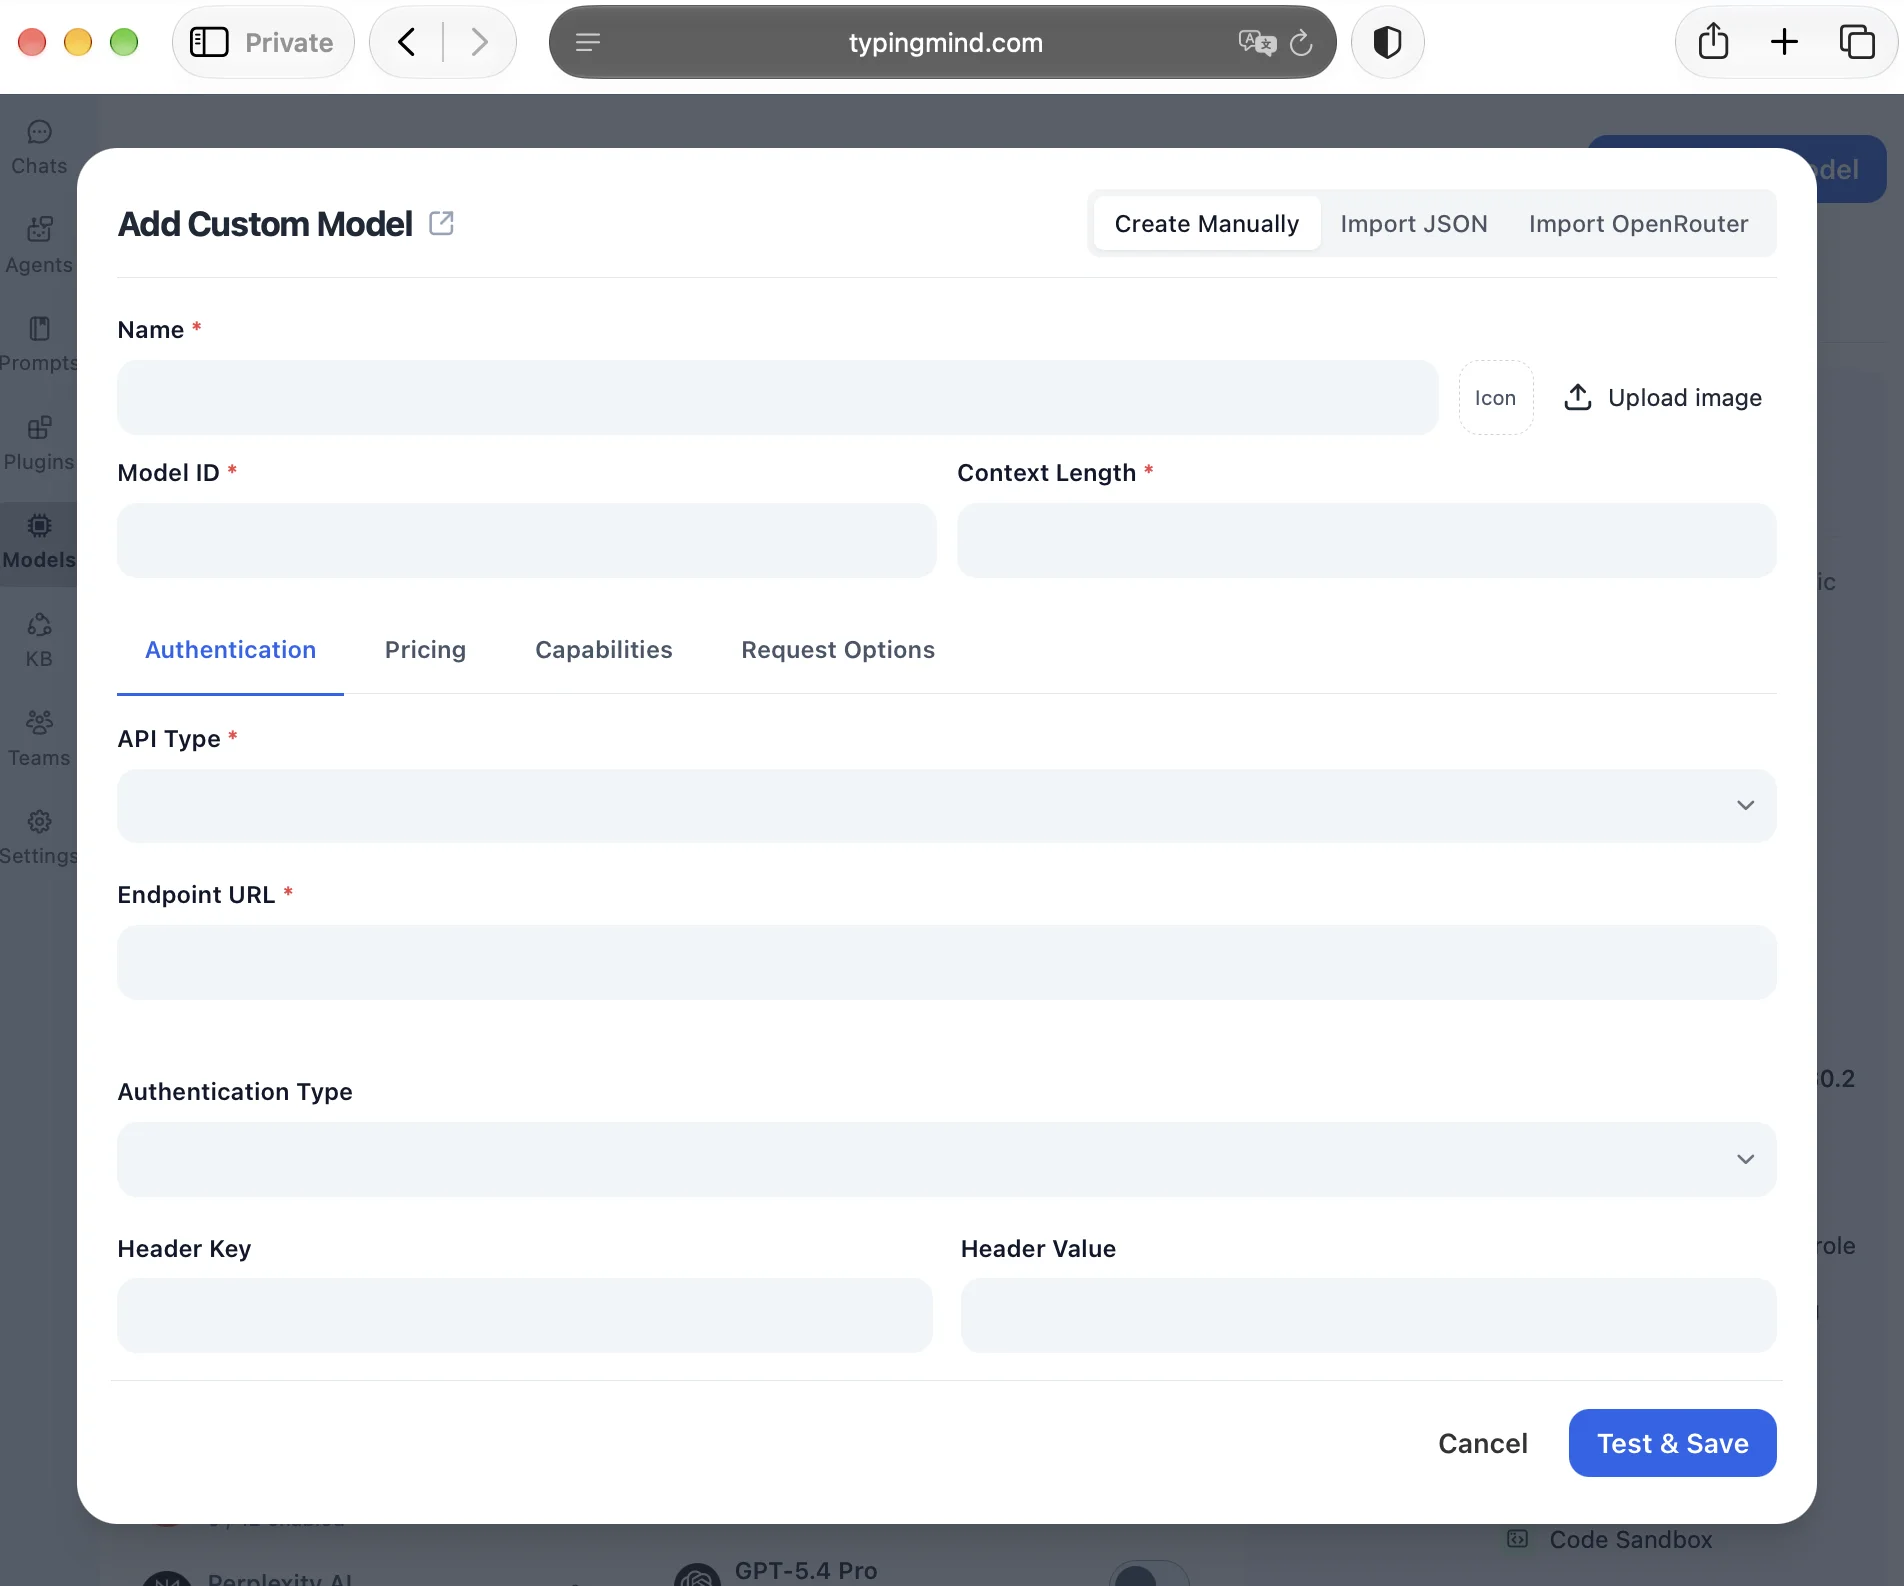
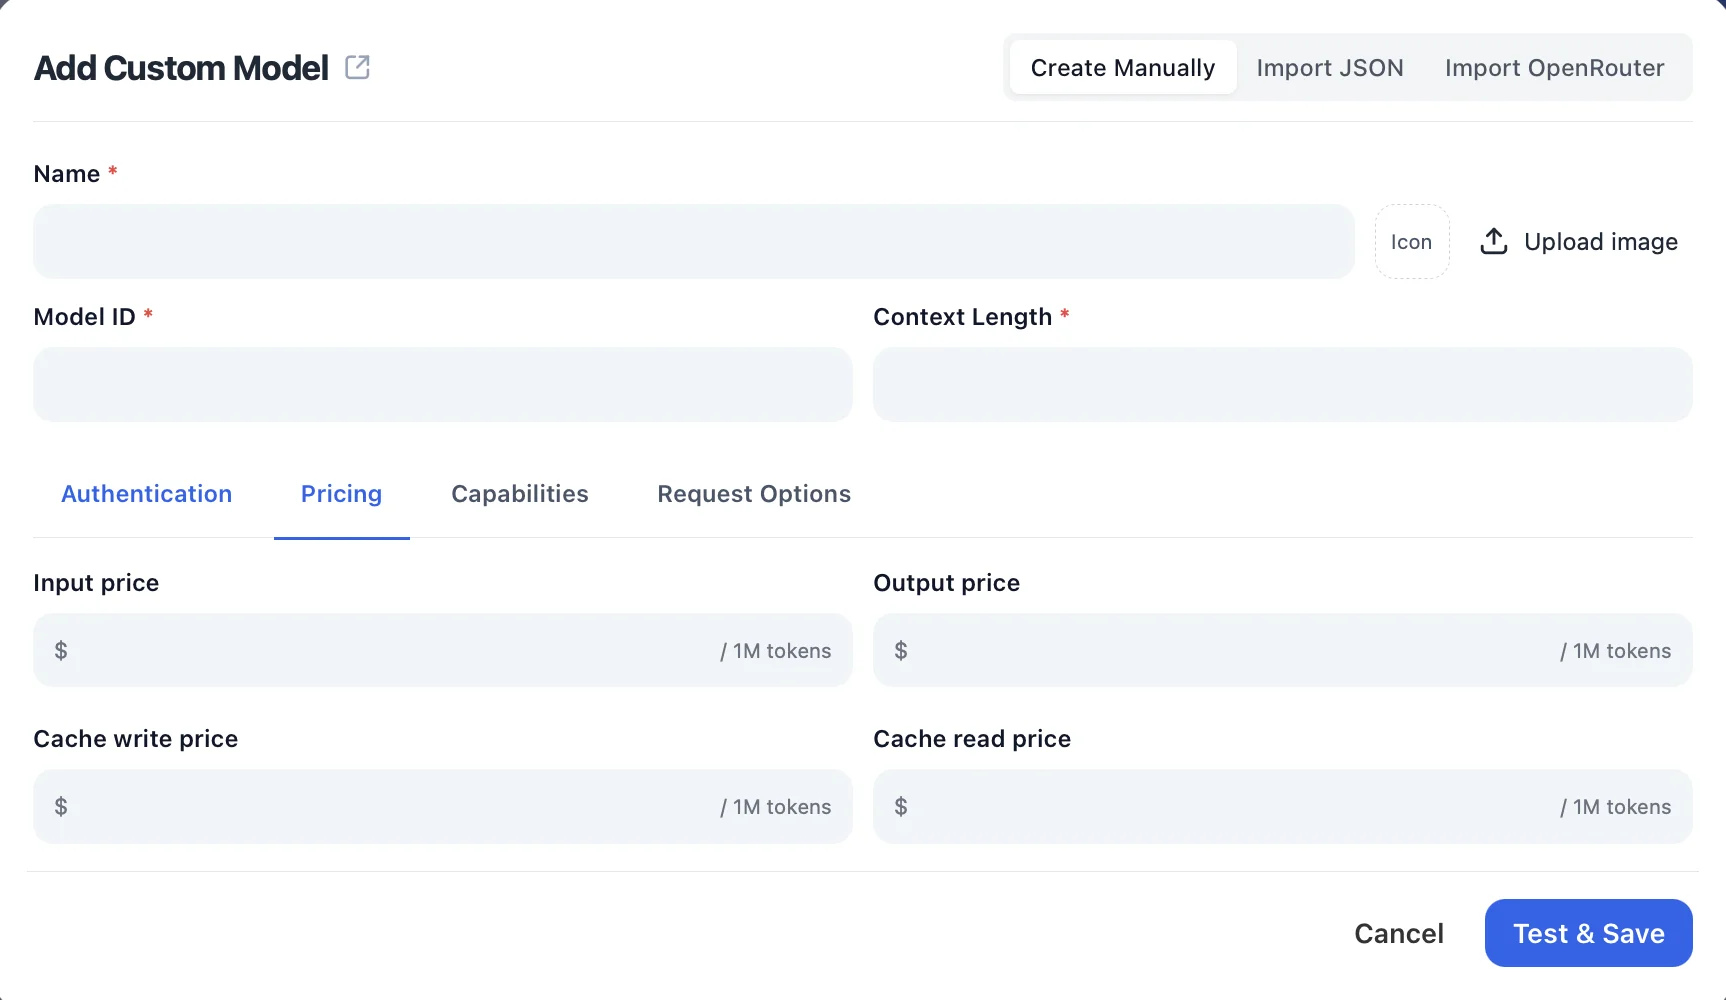
Add pricing (optional)
Open the "Pricing" tab and enter the model's input, output, and cache prices per 1M tokens so TypingMind can estimate your usage costs.
Check the capabilities
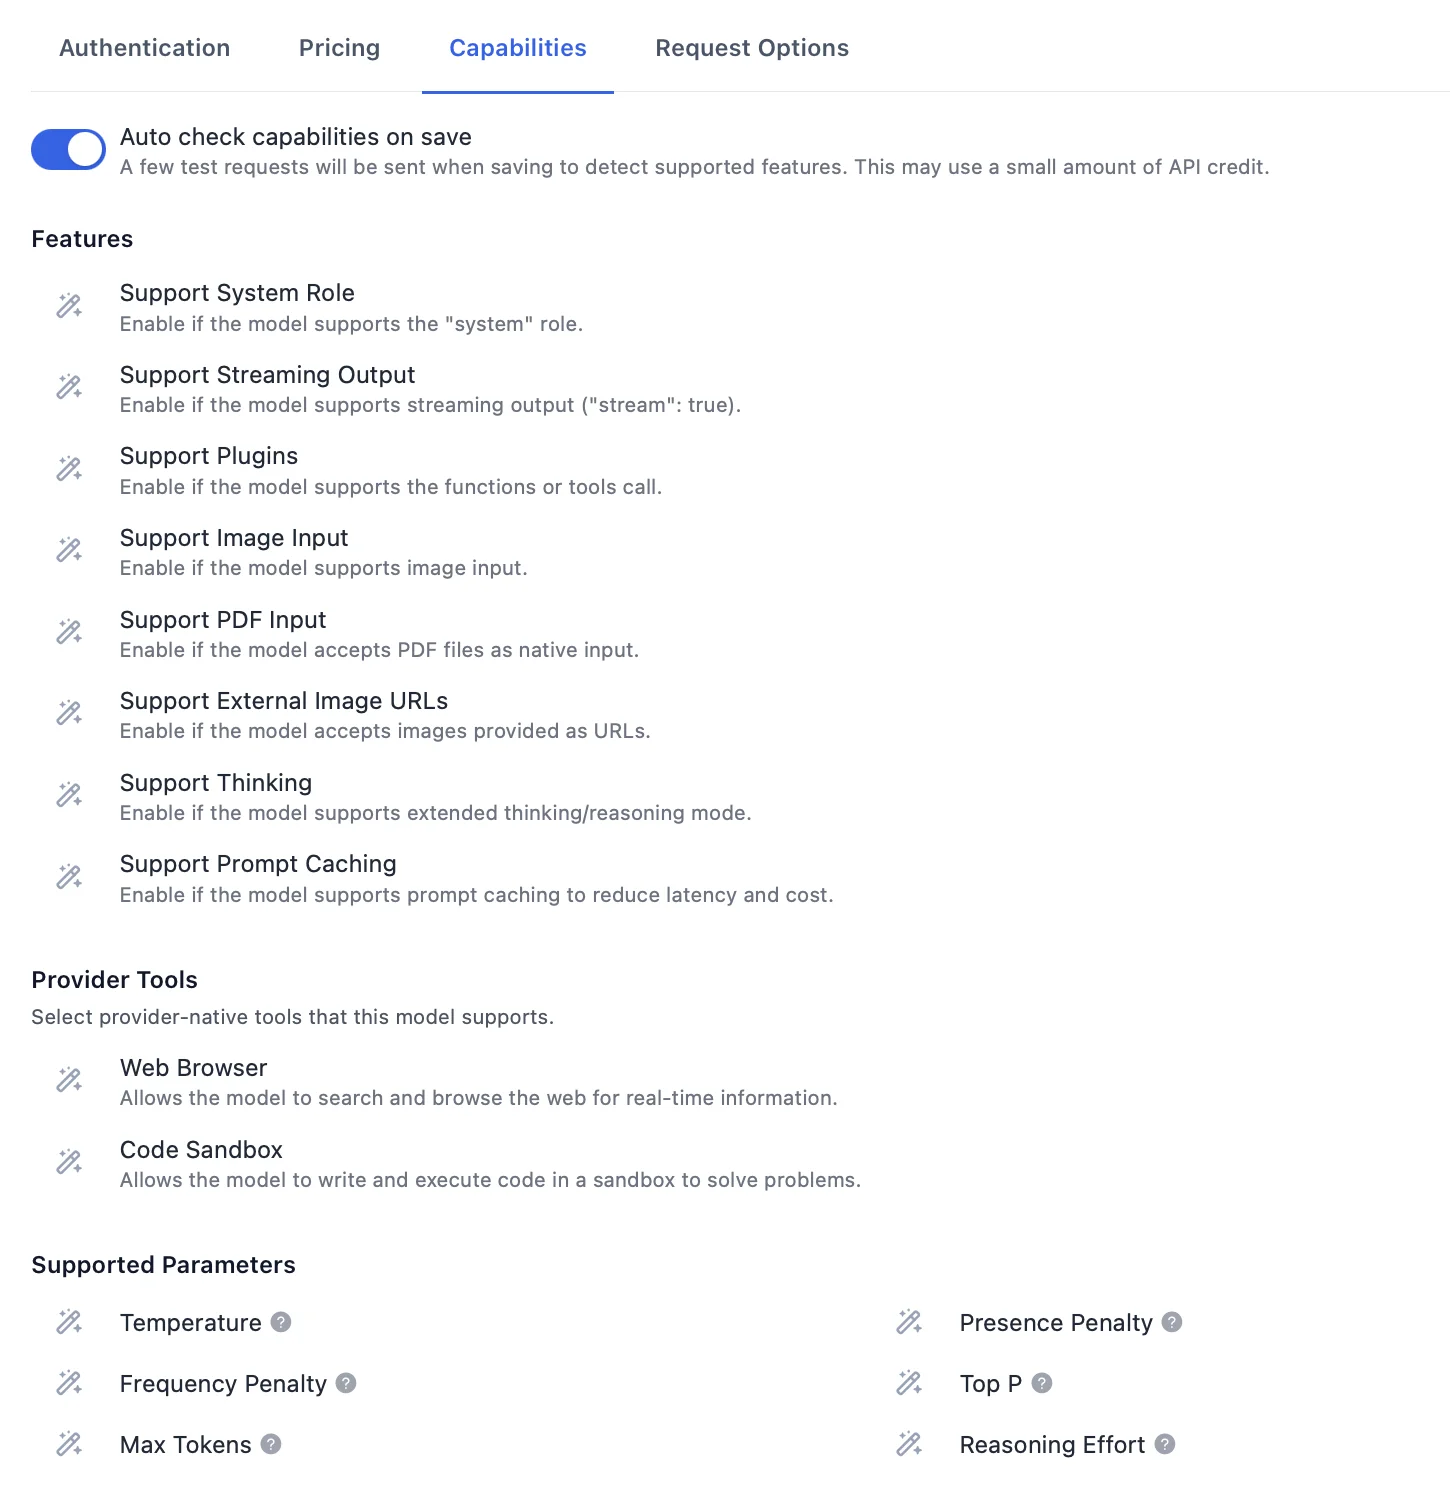
In the "Capabilities" tab, keep "Auto check capabilities on save" on so TypingMind detects supported features like plugins, image input, and thinking, or enable them manually.
Test and save
Click "Test & Save" to verify the connection and add the model.
Start chatting with GLM-4.7-Flash
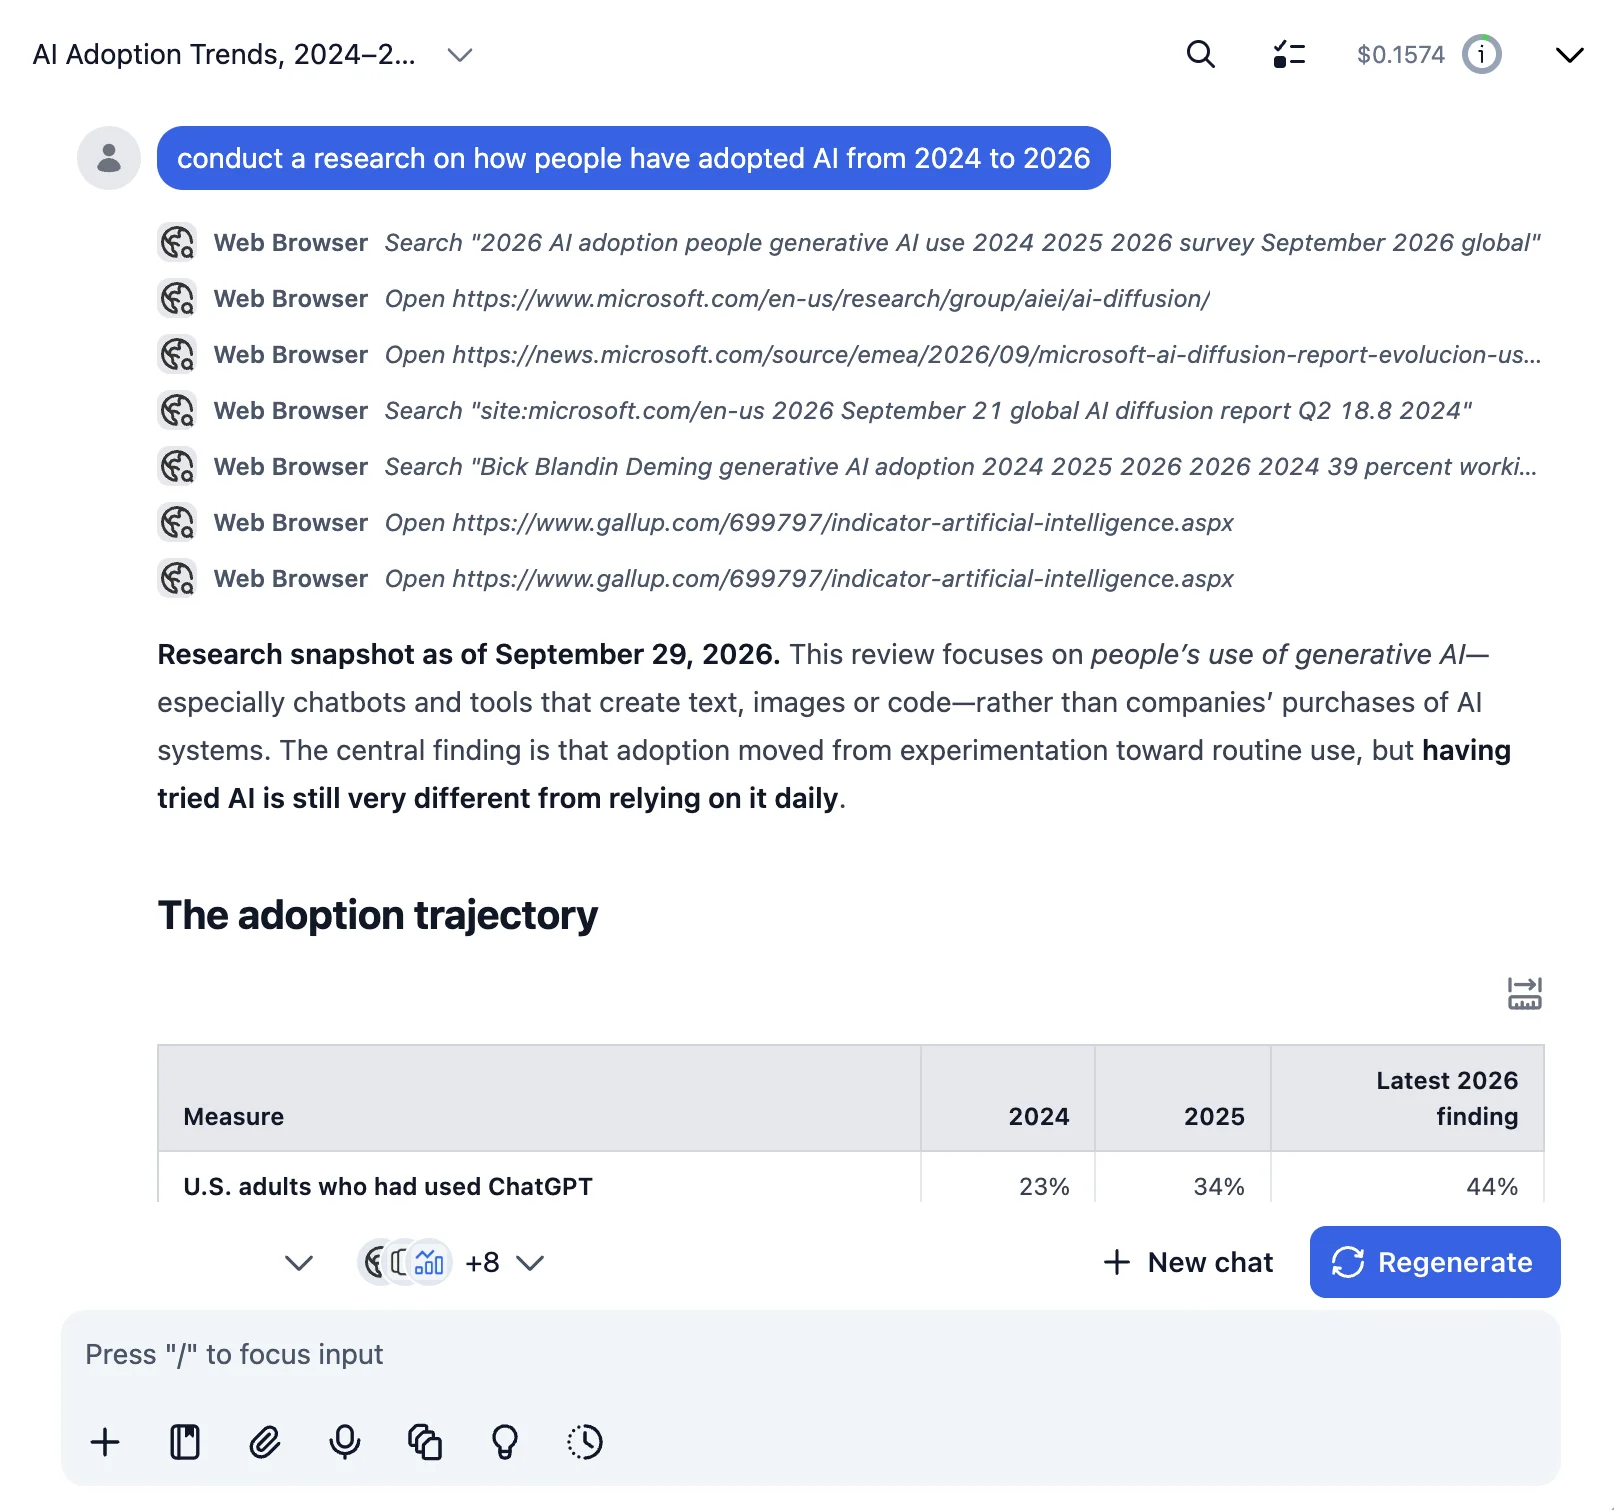
Now you can start chatting with GLM-4.7-Flash through TypingMind:
- Select GLM-4.7-Flash from the model dropdown menu
- Start typing your message in the chat input
- Enjoy faster responses and better features than the official interface
- Switch between different AI models as needed
💡 Pro tips for better results:
- Use specific, detailed prompts for better responses (How to use Prompt Library)
- Create AI agents with custom instructions for repeated tasks (How to create AI Agents)
- Use plugins to extend GLM-4.7-Flash with web search, code execution, and more (How to use plugins)
Why TypingMind + Hugging Face?
Chat with GLM-4.7-Flash and 200+ other models in one workspace, using your own Hugging Face API key.
Best-in-class UI
TypingMind's interface is far superior to standard chat UIs.
Model flexibility
Switch between GLM-4.7-Flash and 200+ models instantly.
Cost control
Pay only for what you use through Hugging Face.
One-time purchase
Buy TypingMind once, use forever with any Hugging Face model.
Data privacy
Your conversations are stored locally by default, not on external servers.
Plugins, MCP, Skills & AI agents
Extend GLM-4.7-Flash with web search, image generation, and custom AI agents.
Frequently Asked Questions
Do I need a subscription to use GLM-4.7-Flash?
No. With your own Hugging Face API key, you pay only for what you use, with no monthly subscription. TypingMind is also a one-time purchase, not a subscription.
How much does it cost to use GLM-4.7-Flash?
GLM-4.7-Flash costs $0/1M input tokens and $0/1M output tokens via Hugging Face. A typical conversation costs around $0.01-0.10, depending on length.
Can I use other models besides GLM-4.7-Flash?
Yes. Any model your Hugging Face API key can access works in TypingMind, and you can switch between it and models from other providers in the same chat.
Is my data private when using GLM-4.7-Flash with TypingMind?
TypingMind stores your conversations locally (in your browser on the web version, on your device in the desktop app). Your messages are sent to Hugging Face with your API key, so check Hugging Face's data policy for how it handles API requests.
What token permissions do I need for the Hugging Face access token?
You need a Fine-grained token with "Make calls to Inference Providers" permission enabled under the Inference section. Optionally, you can also enable "Make calls to your Inference Endpoints" if you use dedicated endpoints.