 TypingMind×
 Gemma3n
How to run Gemma3n locally as private, self-hosted AI
Run Gemma3n from Google as your own private, self-hosted AI. A free local AI tool runs the model on your computer, and TypingMind gives you a full chat app on top of it. Your prompts stay on your machine, and there is no per-message cost.
About Gemma3n: Gemma 3n models are designed for efficient execution on everyday devices such as laptops, tablets or phones.
Gemma3n Overview
| Model | Gemma3n |
| Made by | |
| Runs on |  Ollama |
| Sizes | e2b, e4b |
| Download size | 7.8 GB to 9.8 GB |
| Context window | 32K tokens |
| Input | Text, Image |
| Capabilities | Vision |
| Ollama command | ollama pull gemma3n:e4b |
| Downloads on Ollama | 2.4M |
| Last updated | Oct 14, 2026 |
| Model icon | Get the icon for TypingMind |
Which size of Gemma3n should you pick?
Each size is a different version of Gemma3n. Bigger sizes give better answers but need more memory. Pick the biggest one that fits your computer's RAM. On a Mac, memory is shared with the graphics chip, so leave some room for other apps.
| Model ID | Download | Suggested RAM | Context | Input |
|---|---|---|---|---|
gemma3n:e2b | 7.8GB | 16 GB | 32K | Text, Image |
gemma3n:e4bdefault | 9.8GB | 16 GB | 32K | Text, Image |
Suggested RAM is a rough guide: the download size plus about 2 GB, with room for your system. Longer context windows use more.
Run Gemma3n with Ollama
Ollama is a free local AI tool and the easiest way to run Gemma3n on your computer. The steps below use gemma3n:e4b, the size Ollama downloads by default. Swap in another model ID from the table if you want a smaller or bigger size.
Install Ollama
Ollama is a free, open-source app that runs AI models on your own computer. It is the engine of your self-hosted AI: it downloads Gemma3n, loads it into memory, and answers requests on your machine.
- Download Ollama for macOS, Windows, or Linux from ollama.com/download and open it.
- On Linux, you can install it from the terminal instead:
curl -fsSL https://ollama.com/install.sh | sh
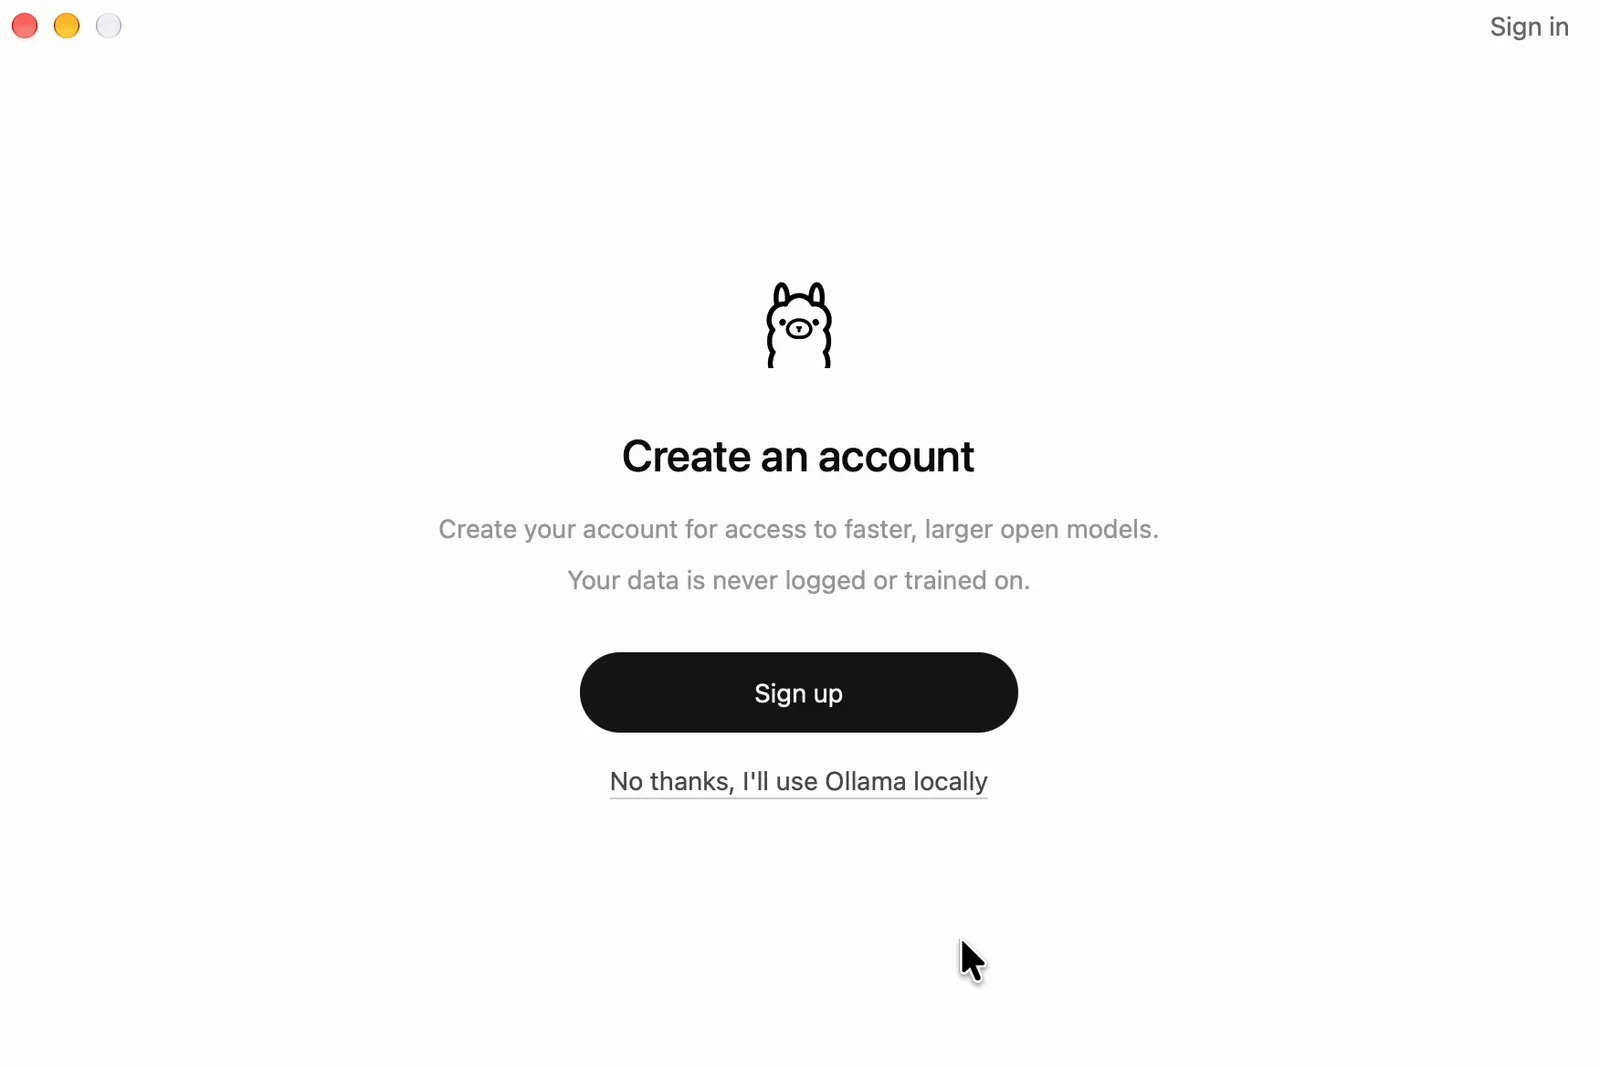
Ollama asks you to create an account. You don't need one to run models on your own computer. Click No thanks, I'll use Ollama locally. Ollama keeps running in the background after that, so you can close its window.
Download Gemma3n with Ollama
Open the Terminal app (Command Prompt or PowerShell on Windows) and run:
ollama pull gemma3n:e4bThis downloads gemma3n:e4b (9.8GB) to your computer. When you see success, the model is ready.
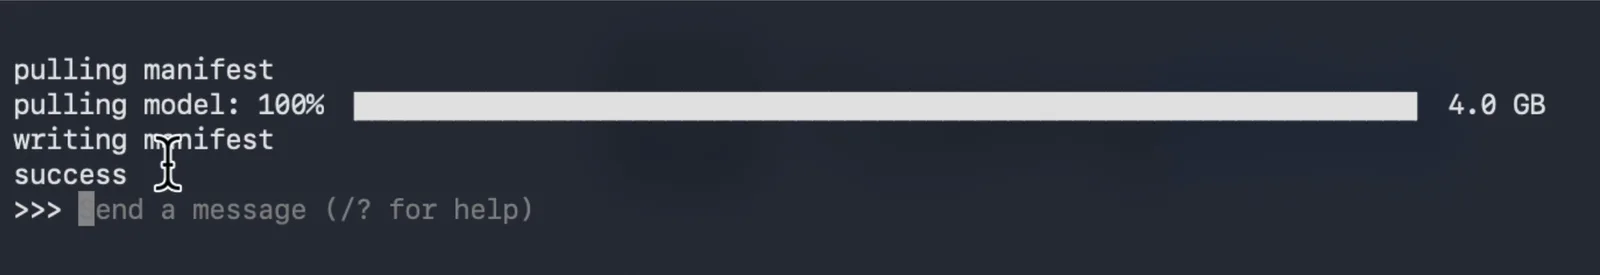
To see what you have downloaded, run ollama list. To see a model's context length and features, run ollama show gemma3n:e4b.
Let TypingMind connect to Ollama
By default, Ollama only answers apps running on your computer. To let the TypingMind web app talk to your local AI, add https://www.typingmind.com to Ollama's allowed origins with the OLLAMA_ORIGINS setting. Your messages still go straight from your browser to Ollama on your computer.
macOS
launchctl setenv OLLAMA_ORIGINS "https://www.typingmind.com"Then quit Ollama from the menu bar and open it again. This setting is reset when you restart your Mac, so run the command again after a restart.
Windows
- Quit Ollama from the taskbar.
- Search Windows for environment variables and open Edit environment variables for your account.
- Add a new variable named
OLLAMA_ORIGINSwith the valuehttps://www.typingmind.com, then click OK. - Start Ollama again from the Start menu.
Linux
Open the Ollama service settings:
sudo systemctl edit ollama.serviceAdd these lines, save, then run sudo systemctl daemon-reload && sudo systemctl restart ollama:
[Service]
Environment="OLLAMA_ORIGINS=https://www.typingmind.com"💡 Give the model more memory for long chats (optional)
Ollama often runs models with a short context window (4,096 tokens on our 24 GB Mac), so long chats forget earlier messages. Raise it to 32,768 tokens in the Ollama app's Settings → Context length, or on macOS with launchctl setenv OLLAMA_CONTEXT_LENGTH 32768, then restart Ollama. Bigger context windows use more memory.
Add Gemma3n to TypingMind
Open www.typingmind.com in your browser. Use the web version: the TypingMind Mac app and the Setapp version block plain http:// addresses like Ollama's.
Click Models in the left sidebar, then Add custom model.
Fill in the form:
| Name | Gemma3n E4B (local)or any name you like |
| Model ID | gemma3n:e4b |
| Context Length | 32768match Ollama's context length |
| API Type | OpenAI Chat Completions API |
| Endpoint URL | http://localhost:11434/v1/chat/completions |
| Authentication Type | No authentication |
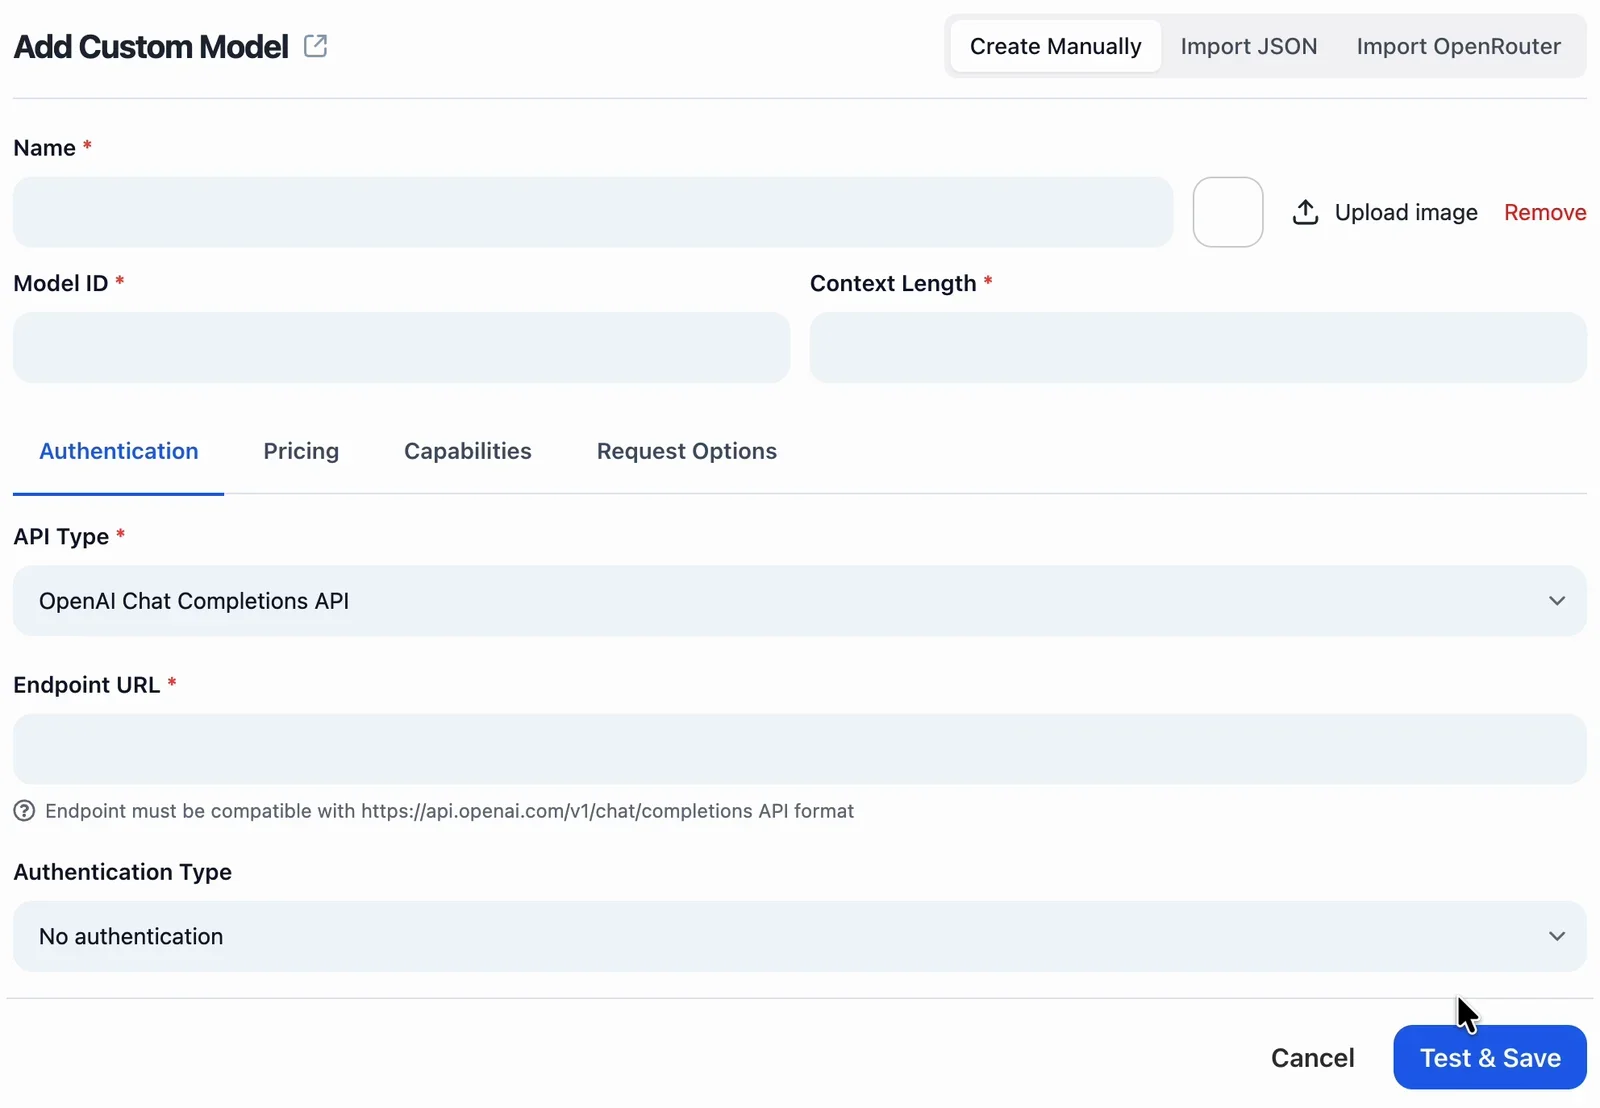 Gemma3n E4B (local)gemma3n:e4b32768http://localhost:11434/v1/chat/completions
Open the Capabilities tab and turn off Auto check capabilities on save. The check sends several test requests, and a local model answers them one at a time, so it can take minutes.
Then set the features for Gemma3n:
- Support System Role: on
- Support Streaming Output: on
- Support Image Input: on
- Support Plugins: off
- Support PDF Input: off
- Support External Image URLs: off
- Support Thinking: off
- Support Prompt Caching: off
Click Test & Save. If your browser asks to let www.typingmind.com access other apps and services on this device, click Allow. This lets the page reach Ollama at localhost.
Chat with Gemma3n in TypingMind
Pick Gemma3n E4B (local) in the model menu under the chat box and say hi. The first reply can take longer while Ollama loads the model into memory. After that, replies come straight from your own computer.
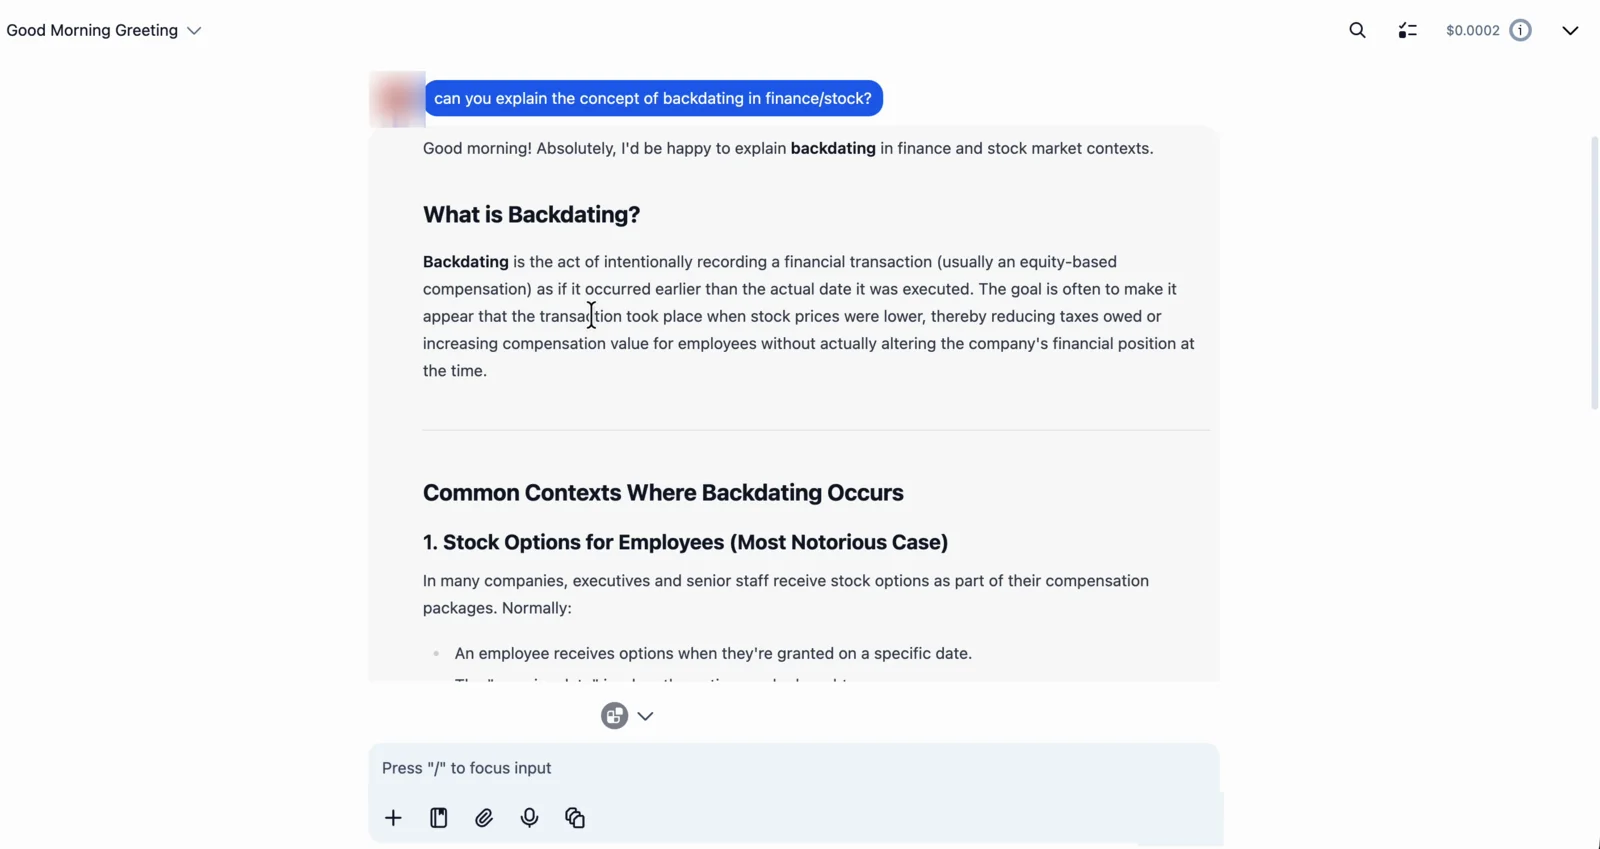 Gemma3n E4B (local)
Send images to Gemma3n
Gemma3n can read images. Click the paperclip under the chat box, attach a photo or screenshot, and ask about it. The image stays on your computer.
You can now use your private AI with TypingMind's chat features: prompts, AI agents, projects, and switching between your local model and cloud models in the same chat.
Tips and troubleshooting
1. The first message of a new chat seems stuck
TypingMind writes a title for each new chat. If the title is made by the same local model, Ollama gets two requests at once and answers them one at a time, so your reply waits behind the title. Go to Settings → Internal prompts, open Advanced Settings under Auto generate title for new chats, and pick another model for title generation, or turn auto titles off.
2. "Could not connect to the API (code: 1)"
TypingMind can't reach Ollama. Check these in order:
- Ollama is running (you see its icon in the menu bar or taskbar).
- You set
OLLAMA_ORIGINSand restarted Ollama afterwards. - You clicked Allow when the browser asked about accessing apps on this device. If you clicked Block, allow it again from the site settings icon next to the address bar.
- You're using TypingMind in the browser, not the Mac or Setapp app.
To check that Ollama is answering, run:
curl http://localhost:11434/api/version3. See what Ollama is doing
Ollama logs every request with its status code (200 means it worked).
- macOS:
tail -f ~/.ollama/logs/server.log - Linux:
journalctl -u ollama -f - Windows: open
%LOCALAPPDATA%\Ollamaand readserver.log
4. Replies are very slow or Ollama runs out of memory
The model is probably too big for your computer. Pick a smaller size from the size table, or close other heavy apps. As a rough rule, you need about the download size plus 2 GB free memory.
Frequently Asked Questions
Is Gemma3n free to run locally?
Yes. Gemma3n is an open model you download once to your computer. Every message runs on your own machine, so there is no per-message cost and no API key to manage.
Is Gemma3n private when I run it locally?
Yes. Your messages go from your browser to the local AI tool on your own computer, not to an AI company. TypingMind keeps your chat history in your browser. If you turn on Cloud Sync, your chats are also backed up to TypingMind's cloud.
How much RAM do I need for Gemma3n?
The smallest size, gemma3n:e2b, is a 7.8 GB download and runs comfortably with about 16 GB of RAM. The default size, gemma3n:e4b, needs about 16 GB. Bigger sizes are smarter but need more memory.
Does Gemma3n work offline?
The model runs fully offline once it's downloaded. The TypingMind web app still needs to load in your browser.
Can Gemma3n use TypingMind plugins?
Gemma3n isn't listed with tool calling, so keep Support Plugins off. Pick a model with tool calling if you need plugins.
Can Gemma3n read images?
Yes. Gemma3n accepts images, so turn on Support Image Input and attach images in the chat.
Why is the first reply slow?
The local AI tool loads the model into memory on the first message and keeps it there for a few minutes. Later replies start faster.
Does TypingMind run locally?
TypingMind runs in your browser at www.typingmind.com, and your chats are stored locally in your browser by default. When you chat with a self-hosted model, your messages go straight from your browser to the model on your own computer, not through TypingMind’s servers. If you turn on Cloud Sync, your chats are also backed up to TypingMind’s cloud.
Can I self-host TypingMind?
Yes. To self-host TypingMind for your team or company, use the self-hosted version of TypingMind Teams. You run it on your own servers next to your self-hosted models, so chats, users, and settings stay inside your own infrastructure. Contact our sales team to get started.